Tailyr AI Concierge
A grounded, multi-store RAG assistant for high-value retail
My role: Lead developer for the platform: RAG pipeline, multi-tenant API, partner dashboard and the LLM-judged QA harness.
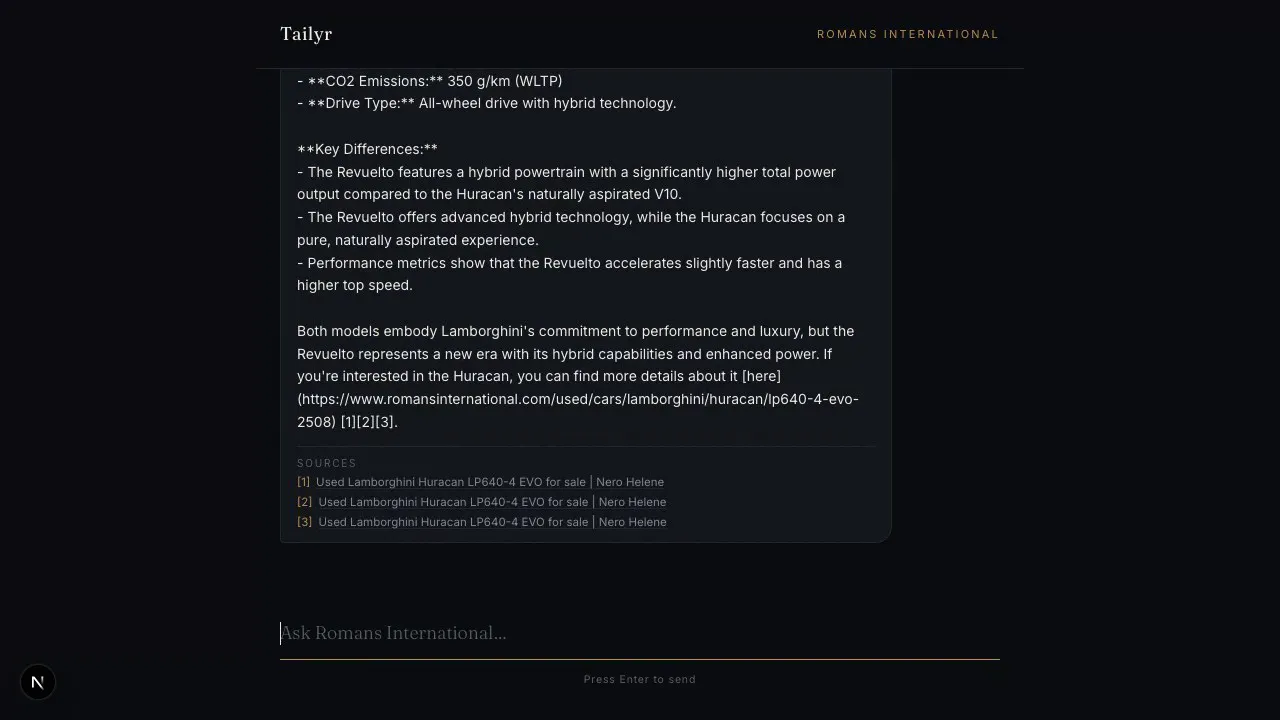
Client work for Tailyr. Details are limited to what already appears in the public demo recording.
Overview
Each store gets an assistant that answers strictly from that store's crawled website, uploaded documents and partner-supplied answers, cites every claim, and refuses to guess. Unanswered questions are logged for the store team, and their answers are embedded back instantly.
The problem
Luxury car dealers, watch retailers and high-end audio stores cannot afford an assistant that invents stock, prices or availability. Off-the-shelf chatbots hallucinate and mix up tenants.
The solution
A retrieval pipeline with two confidence gates blocks outside knowledge. Every answer carries numbered citations to the store's own pages. Store isolation is enforced at the data layer, and a human-in-the-loop knowledge base turns each unanswered question into a permanent, attributed answer.
Principal features
Strictly grounded
Two confidence gates and per-source citations on every answer.
Knowledge loop
Unanswered questions go to a partner dashboard; answers are embedded back and attributed to the team member.
Store isolation
Multiple brands on one platform; a store can never see another store's data.
Sold-stock intelligence
Knows what was previously sold for comparisons but never offers it as available.
Manufacturer fallback
For models not in stock, quotes approved manufacturer pages and offers to source the item.
Adversarially tested
A sixty-question stress set covering prompt injection, pricing pressure and privacy probes.
Technical decisions
- pgvector on Supabase keeps embeddings next to the relational data, so tenancy is one row-level policy rather than two systems to keep in sync.
- An LLM-judged QA harness scores every release against a fixed question set; the last full run passed 316 of 337 cases (94%).
- Booking intent is detected up front and handed to a human as a lead instead of being handled by the assistant.
More AI & Automation
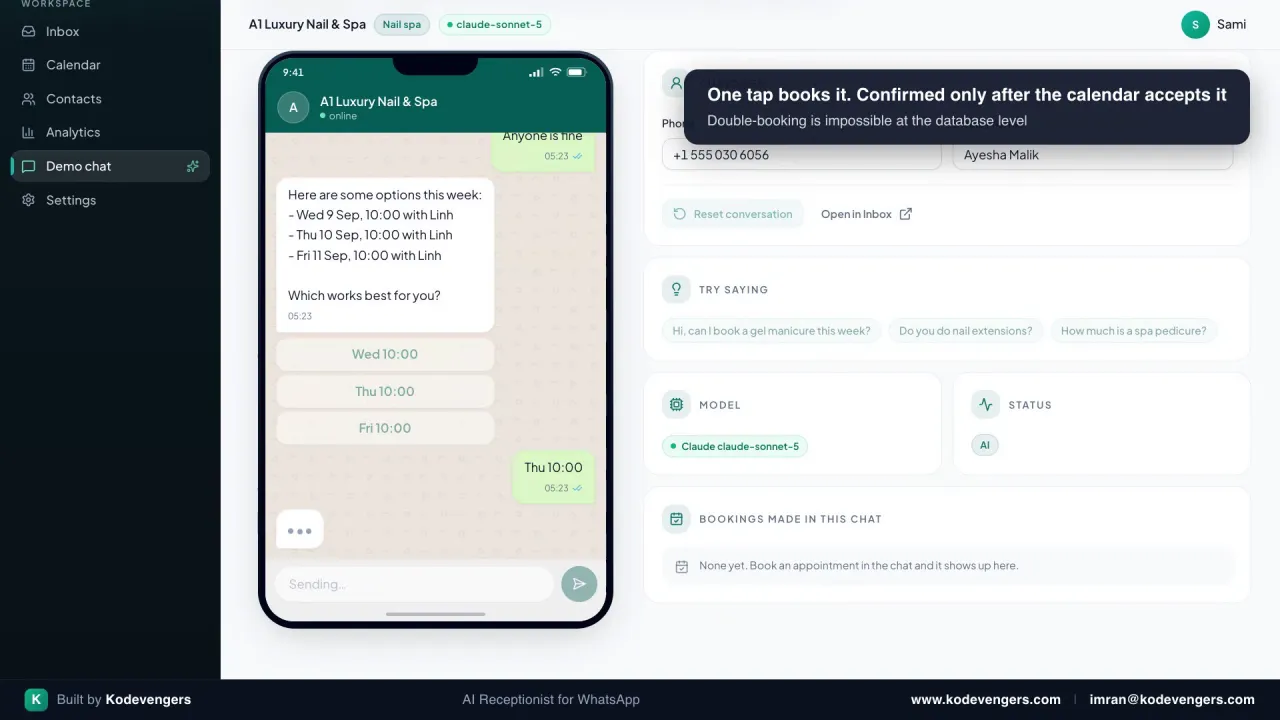
AI Receptionist
A 24/7 WhatsApp booking agent for appointment-based businesses
View project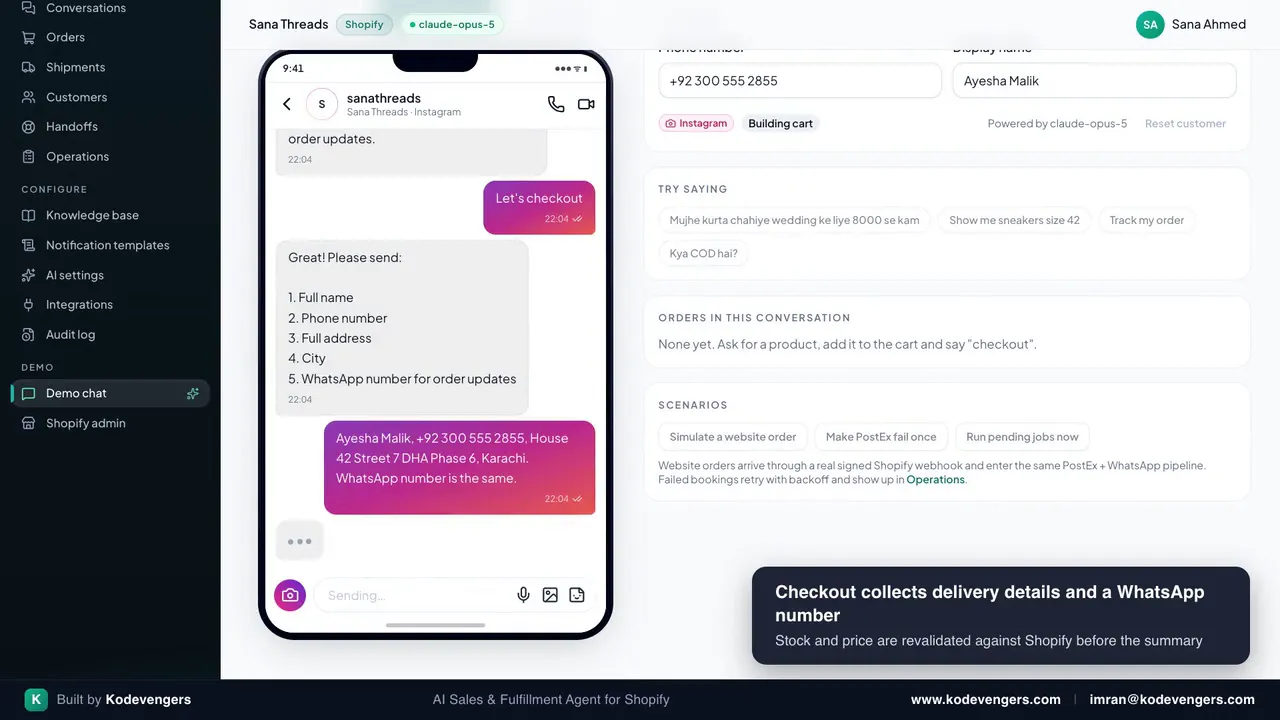
AI Shopify Sales Agent
Selling and fulfilment inside WhatsApp, Instagram and Messenger
View project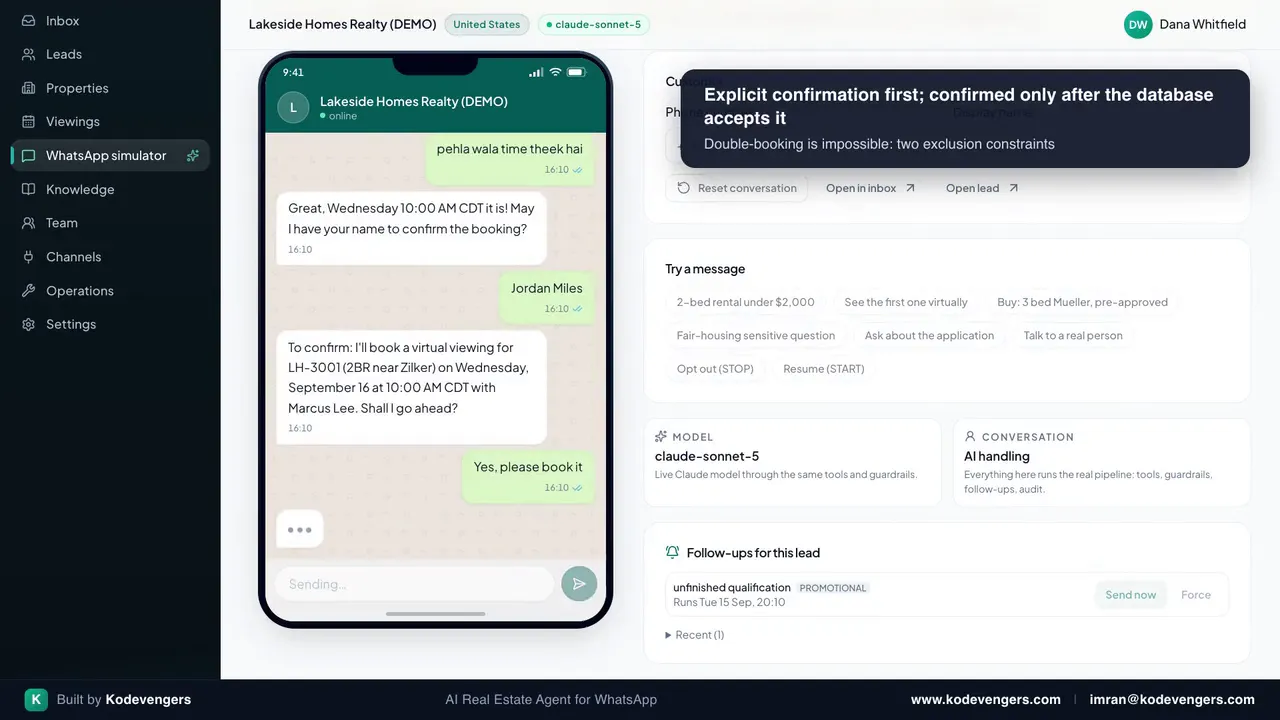
AI Real Estate Agent
Qualifies buyers on WhatsApp and books viewings that are genuinely free
View project